
A control plane for autonomous AI agents: every consequential action passes identity, policy and human approval, with a signed receipt.
Hard spending caps for LLM APIs: a pre-flight check blocks an over-budget call before it is sent or billed.
https://noburn.dev
Showing the product's mark because a screenshot isn't available yet. Own this product? Suggest a screenshot.
noburn is a guard that sits in front of your LLM calls. Before each request leaves your process, it runs a check against a budget and returns allow or refuse with the estimated cost and remaining balance — so a call that would blow the cap is never sent to the provider and never billed, rather than being caught in next month's invoice.
The problem it names is agent-specific: agents do not fail by falling over, they keep working correctly at a cost nobody is watching. The site walks through the shapes that do it — a retry loop that runs all night, context that compounds so turn forty costs twenty times turn one, and a runaway batch — and offers three limits checked on one request: per-user, per-run and per-project.
It ships as two SDKs, `@noburn/sdk` on npm and `noburn` on PyPI, both listed at version 0.1.0 under MIT with zero additional dependencies, plus a `bench-check.mjs` script in the repo for measuring the added latency against your own project. The site is explicit that it is pre-launch and has no customer logos yet, and publishes a worked example of a refused call.
Teams running LLM or agent workloads in production who need a hard budget ceiling on the request path.
Capping spend per user, per run and per project; stopping an infinite retry loop from billing all night; guarding agent runs with compounding context; adding a budget check to an existing LLM integration.
Freemium
Individual plan prices are not publicly listed. Check the official site for current pricing.
Start free with a sign-up that carries a plan choice — the site links a Starter plan and a Pro upgrade. SDKs are published at 0.1.0 (npm and PyPI) under MIT, and the project describes itself as pre-launch. Plans are priced under a per-incident framing on the pricing page.
Pricing and availability last checked: Oct 24, 2026 · Source: official website
Refuses before the request leaves your process, which is the only point at which a runaway agent can actually be stopped, and the SDKs add no dependency tree to a hot path.
Pre-launch at version 0.1.0, and the site states plainly that there are no customer references yet.
For anyone building with LLM APIs: noburn sets spending limits before the API call is made, so an over-budget request is never sent and never billed. Worth exploring if you are building AI agents or LLM-powered apps.
This is an editorial choice, not an objective ranking or score. Read the issue.
A control plane for autonomous AI agents: every consequential action passes identity, policy and human approval, with a signed receipt.
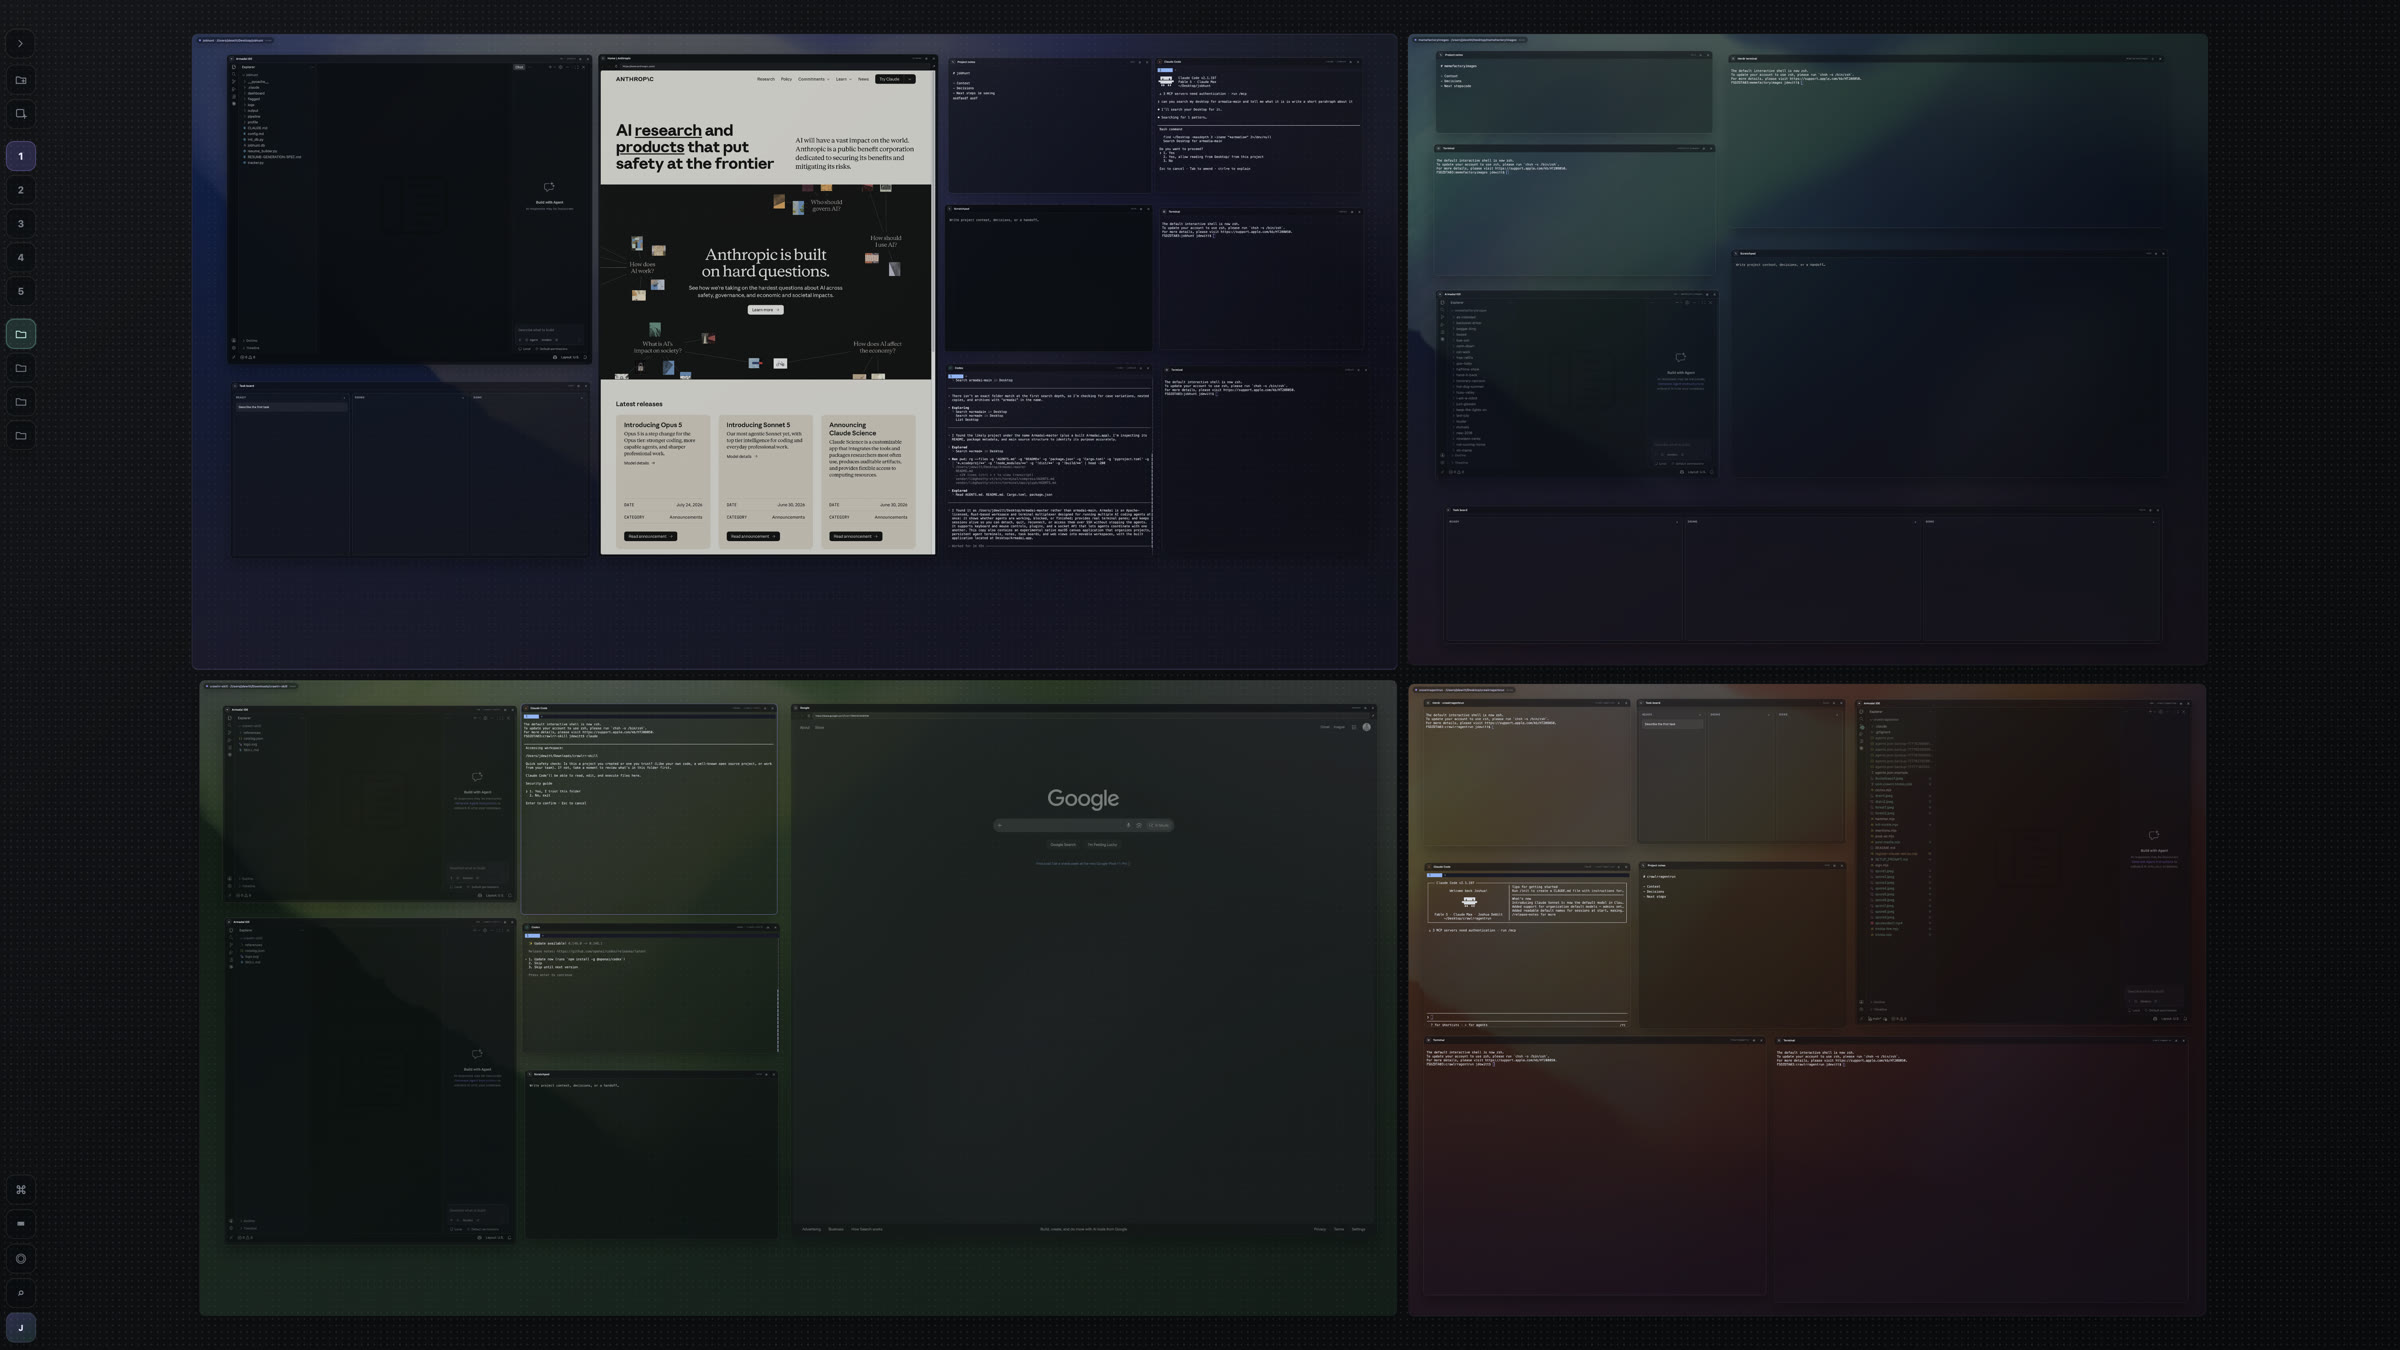
An infinite canvas for Mac that holds your projects, your AI coding agents and your tools in one workspace.

An IP intelligence API that tells you where an address is and who operates its network.
An AI gateway for OpenAI and Anthropic apps that tracks usage, enforces per-user budgets and manages provider keys.